Hotel Lobby AI Prompt: Copy It, or Skip It With Photos
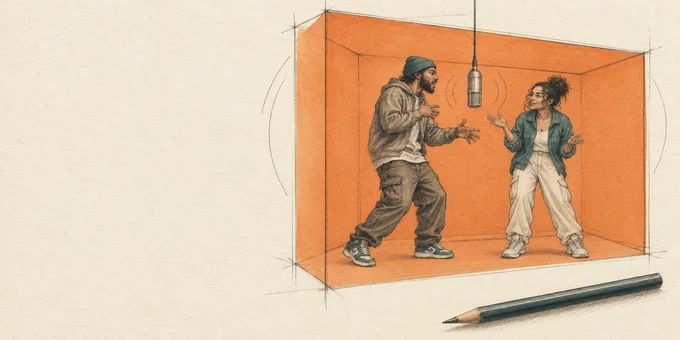
A Hotel Lobby AI prompt has to pin down four things: a plain orange booth, one mic hanging between two people, which photo stands on which side, and who raps while the other hypes. Leave one out and a model may add a halo, swap the two sides or invent a third person.
Updated
The production notes
Hotel Lobby AI prompt
Every instruction has a job.
- Set
- Cast
- Sound
The prompt below is the one RapVideo sends to Wan 3.0 for a two-person rap of your words in the booth, printed from the same code the server runs. It is in Chinese, like every Wan 3.0 prompt we send; the table under it says what each line asks for in English. On RapVideo you never type it: you add two photos and the booth is built in.
Copy this Hotel Lobby AI prompt
This version is for a vertical 12-second Hotel Lobby video in which both people rap about the topic. It goes out with three attachments: 图1 and 图2 (image 1 and 2), the left and right photo, each first redrawn as a full-length studio portrait of the same person, and 音频1 (audio 1), the Hotel Lobby track cut to the same length, kept only as the beat. There is no reference clip: the orange booth, the framing and the routine’s best-known moves are written out instead, because in our test the clip’s mouths, timed to the original lyrics, fought the new words. So it also works in a tool that takes no clip. The other three stages send the same prompt with a different scene: a hotel lobby, a neon vocal booth or a graffiti wall. Before it goes out, an AI turns what was typed in the box into rhyming lines on the beat and reads a voice for each person off the photos; here the topic "Lena and Tom, ten years of Sunday pancakes" became the 6 lines you see, with their seconds and who raps each.
一段 12 秒的录音棚说唱视频。场景:纯橙色的无缝背景墙铺满整个画面,柔和均匀的棚拍光,没有阴影,画面里没有任何别的物件。一支银色复古录音棚麦克风从天花板用细杆垂下来,悬在左边那个人的嘴前。

构图:竖版画面,两人肩并肩挤在画面中间,几乎挨着,身体侧过来以四分之三侧面对着对方,两个人都完整在画面里;镜头在正前方,全程拍到腰部以上,不拉远。

左边的表演者是图1里的主体,右边的表演者是图2里的主体。脸、发型或毛发、身材和衣服都来自照片,从第一帧到最后一帧都不变。主体如果是动物,就像人一样用两条后腿直立站着,用前爪做手势,保持本来的样子,不加衣服。忽略照片的背景。

动作:幅度小、松弛,像在录音棚里随口对唱,跟着节拍点头、晃身体,不要夸张的舞蹈。按先后顺序有这几个动作:开头右边的人伸直手臂指向左边的人;中间右边的人抬起手腕低头看,像在看表;接近结尾右边的人转过身背对镜头,手臂在脸前摆一下,再转回来;最后两人面对面,各竖起一根食指放在嘴前比"嘘"。

声音:用音频1的伴奏(鼓点、808 低音和旋律)作为整条视频的背景音乐,从头响到尾,节拍和音频1一致。音频1里原来的人声和歌词一个字都不要用,只留伴奏。

说唱:两个人轮流说唱,按下面的时间一句接一句地唱,一句一小节,每句从这一小节的第一拍唱起,压在伴奏的节拍上:0–2.1 秒左边的人唱「Ten years of Sundays, Lena’s on the pan」;2.1–4 秒左边的人唱「Batter on the counter, that’s the Sunday plan」;4–5.9 秒右边的人唱「Tom flips the stack like a pancake man」;5.9–7.7 秒右边的人唱「Syrup on the ceiling, catch it if you can」;7.7–9.6 秒左边的人唱「Lena and Tom, still the breakfast clan」;9.6–11.5 秒左边的人唱「Ten more years, same table, same old pan」。左边的人用成年女声,右边的人用成年男声,两个人的声音一听就不一样。不唱的人跟着节拍点头、做动作。换人的时候,刚唱完的那个人在旁边喊一声简短的附和(yeah、uh、let’s go 这类),比歌词小声。一字不改地照着唱,用歌词本身的语言。说唱要快、要密:每拍差不多三个字,一句紧接一句,几乎不停顿,带弹跳感的切分节奏,咬字干脆有力,像真正的 trap 说唱,嘴型和每一个字精确同步。

橙色铺满整个画面,没有黑色或暗角。不要分屏,不要多余的人,画面上不要字幕或文字。人脸从头到尾保持一致。
The default video, with the original Hotel Lobby song, uses a different prompt on the same model. It adds a silent reference clip of the booth performed by two AI stand-ins and asks Wan 3.0 to copy the clip’s framing and moves, keep the track as the whole soundtrack, and have the left person rap its vocal in sync while the right one hypes.
No prompt needed
Or let RapVideo write the prompt for you
The booth, the moves and the sound are built in. Add a photo of each person and check the price on the button.
Your two performers
One person each. Left raps, right hypes.
Stage
Sound
Try it free first, one per account. The full 12-second video is 6 credits at 480p. View pricing
Line by line: why each instruction is there
| Line | What it prevents |
|---|---|
| A seamless plain orange wall filling the frame, soft even light, nothing else in the picture | A dark studio, props or a different set |
| One silver vintage studio mic hanging from the ceiling, in front of the left person’s mouth | A mic on a stand, two mics, or a mic nobody raps into |
| Shoulder to shoulder, turned three-quarters toward each other; waist up in a vertical or square frame, knees up in a wide one; no pulling back | A wide shot with small faces, or a person cut off at the edge |
| Left performer from 图1, right from 图2; face, hair, body and clothes from the photos, the same from first frame to last; ignore the photo backgrounds | The two trading places, faces changing halfway, and pieces of your photo backgrounds leaking in |
| An animal stands on its hind legs like a person and gestures with its front paws, as it is, with no clothes added | A pet on all fours, or a pet in someone else’s clothes |
| Small, relaxed moves in order: the point, the watch check, the turn, the shush (the 15-second cut adds a hand shading the eyes); an order, no seconds | A big dance instead of the booth’s gestures; a version with seconds was followed loosely in our test |
| The beat of 音频1 (drums, 808 bass, melody) from start to end; none of its vocals or lyrics | The original rap playing over your words, or a beat that drops out |
| Each line with its seconds and who raps it, starting on the beat, rapped word for word | Lines drifting off the beat, the wrong person rapping, or the words rewritten |
| Both rap: the two take turns, each in a named voice (here an adult woman and an adult man) | Two people rapping in the same voice |
| Rap the lines word for word, in their own language, fast and dense: about three syllables a beat, one line straight after the other, mouths in sync | A slow, sparse verse, words swapped for others, or lips that miss the words |
| At each hand-over, the one who just rapped calls out a short “yeah” or “let’s go”, quieter than the lyrics | Dead air between the two rappers |
| Orange fills the frame; no split screen, no extra people, no captions | Black edges, panels, a third face and burned-in text |
Adapting the prompt to another AI video model
- Use an AI video model that takes two reference images and an audio track. This prompt needs no reference clip.
- Rename the attachments the way your tool expects. This prompt calls them 图1, 图2 and 音频1; RapVideo’s Seedance prompts for the sung songs and effects name them in words, such as "reference image 1", and other tools use their own tags. Keep the left photo first.
- Change the framing paragraph, the second one, to the format you pick: RapVideo writes waist up for 9:16, 3:4 and 1:1, and knees up for 16:9 and 4:3.
- One rapper instead of two: RapVideo swaps the rap paragraph for one in which the left person raps every line while the right one nods, gestures and calls out now and then.
- Swap in your own lines, one for each time slot: 0–2.1, 2.1–4, 4–5.9, 5.9–7.7, 7.7–9.6 and 9.6–11.5 seconds in a 12-second video, on the Hotel Lobby beat (about 129 BPM). On RapVideo an AI writes them for you from the box, which takes up to 1000 characters and cannot be left empty.
- For the original track instead of an AI rap, attach the audio and ask the left performer to lip-sync it. Only use a recording you have the right to use.
Hotel Lobby prompts published elsewhere
Dreamina's Hotel Lobby AI filter page publishes three copy-and-paste prompts for Seedance 2.5 (friends, pets and adult siblings), each about 75 words. They fix one subject per side, a hanging mic, a locked full-body camera and a list of things to avoid, but none asks for a song or lip-sync, and one sets the duet in a terracotta studio. A prompt-only site we checked describes a marble lobby with chandeliers, which is not the trend at all, and renders no AI video.
On RapVideo the prompt and the sound are already set for every Hotel Lobby video: the Hotel Lobby AI booth takes two photos, an AI rap generator writes the verse, and Migos AI is the same trend under its other name.
When the render drifts: symptoms and prompt fixes
| Symptom | Fix in the prompt or the photo |
|---|---|
| A face drifts toward someone else | Front-facing, well-lit photos, waist up; keep "face, hairstyle and outfit" |
| The two swap sides | Name the left and right performer with their image number |
| A third person appears | Keep "no extra people" and "ignore the photo backgrounds" |
| Text shows up on screen | Keep "no captions or text on screen" |
| Lips miss the words | Attach audio that starts on a word, or let the model write the rap |
Free routes that use a prompt like this are covered in Hotel Lobby AI free.
FAQ
Will this prompt work in Dreamina or Kling?
We have only run versions of it through RapVideo. In another tool, rename the attachments to its syntax and expect to retry; the moves come from the written order, so they will follow the trend less closely than a reference clip would.
Does the prompt use the original Hotel Lobby song?
As the beat only. It attaches the Hotel Lobby track of the same length as 音频1 and asks for its drums, bass and melody without its vocals or lyrics, a recording that belongs to its rights holders. The default RapVideo video keeps the whole track, vocals included, and the lead lip-syncs it.
Why 图1 and not a tag like @Image1?
Wan 3.0 requests are written in Chinese and name attachments 图1, 视频1 and 音频1 (image, video, audio). Our Seedance requests, for the sung songs and effects, name them in words, such as "reference image 1", which reads the same whatever tag syntax a model expects.
Does RapVideo ask for a prompt before it makes a Hotel Lobby video?
No. You add two photos and press Create video; the prompt is built for you. A 12-second 480p video is 6 credits.
Sources
Read next
Hotel Lobby Trend: How to Do It in Minutes From Two Photos
Three ways to do the Hotel Lobby trend (two photos and AI, a CapCut template, filming it yourself), with steps, free options and posting tips.
Hotel Lobby AI Free? Free Routes and Their Catches
What CapCut templates, Dreamina, Higgsfield and phone apps give away for the Hotel Lobby AI trend, checked on October 2, 2026.
RapVideo is an independent tool, not affiliated with Quavo, Takeoff, Migos, Quality Control Music, Motown or COLORS.
Watch
Hotel Lobby AI prompts on YouTube and X
Videos and posts from creators and other tools, each credited and linked to the original. Nothing loads from YouTube until you press play.